Field note · implementation
Why Does an AI Workflow Become Slower After Human Review?
A runnable worksheet shows when human review adds more queue demand than an AI workflow can absorb, and when threshold routing is safer.
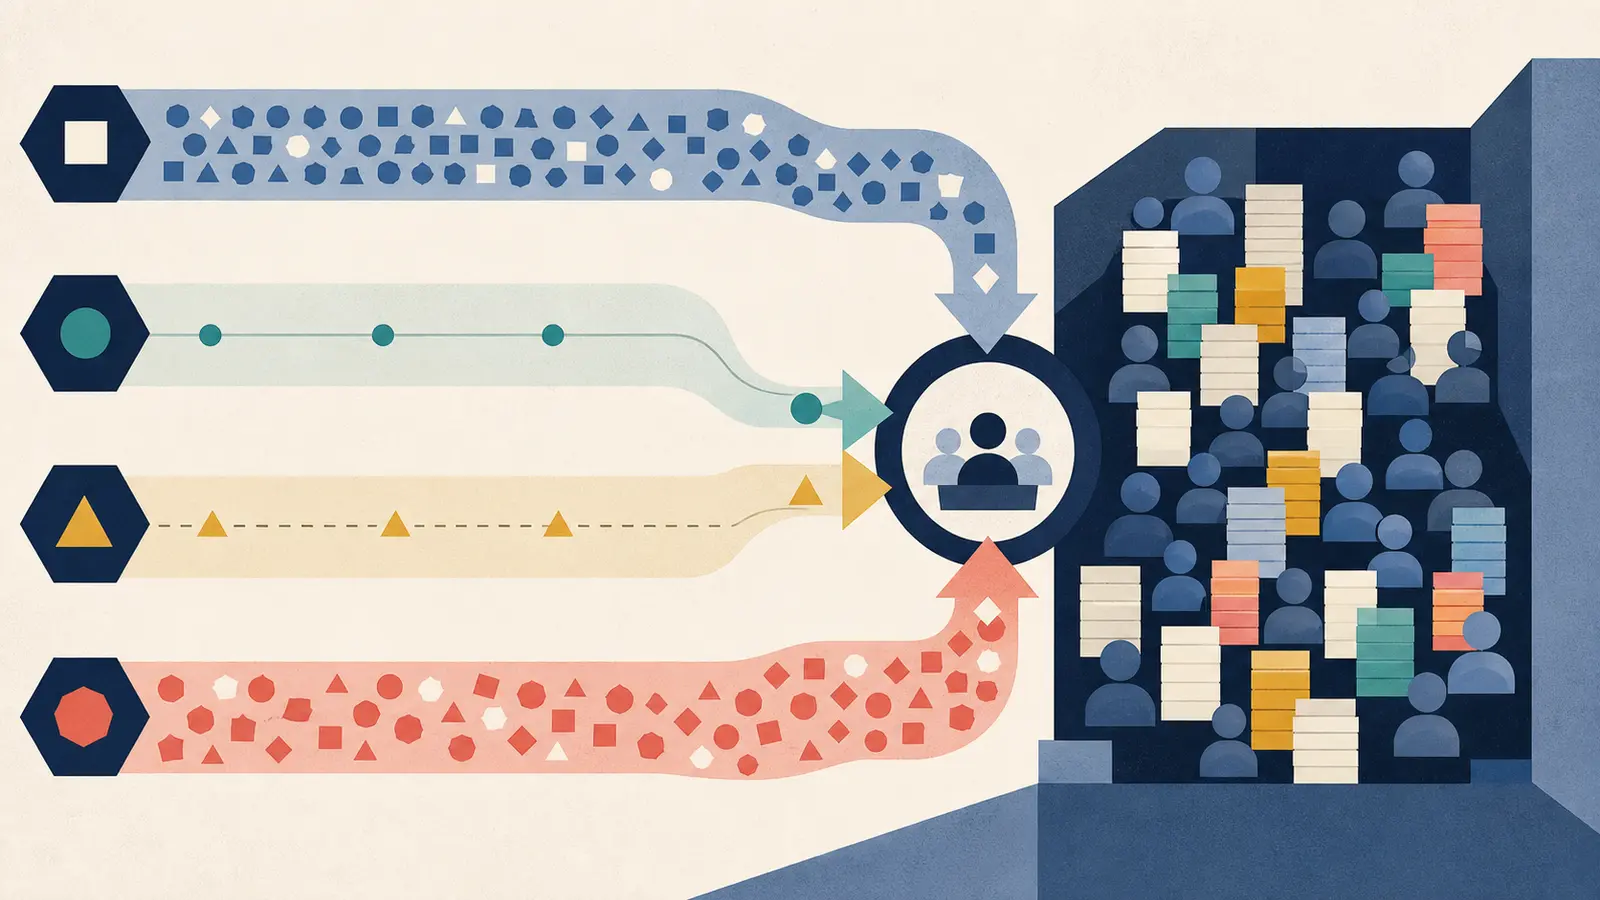
Adding review can make the model look faster and the workflow feel slower. The model finishes its draft quickly, but every routed item now competes for reviewer minutes. If some errors escape and return as correction work, the same people carry a second queue.
What changes when review is added?
The workflow slows when review demand plus expected rework approaches the human capacity available in the same time window. Draft latency is only one part of the system.
The supplied queueing research describes this as a gap between mean task speed and system-level delay: a fast first draft can still worsen congestion when errors return as downstream rework. (Queue & AI: When Faster Tasks Slow Down the Workflow)
The practical diagnostic is small enough to run before you redesign the workflow:
review demand = arrivals/hour × review fraction × mean review minutes
expected rework = arrivals/hour × escaped-error rate × rework minutes/error
total human attention = handling minutes + expected rework
utilization = total human attention / available human minutes
If utilization reaches 1.0, the model is not the only problem. The human station cannot clear the expected work as it arrives. Even below 1.0, a high utilization level leaves little room for bursts and long reviews. The worksheet uses 80% as a configurable warning threshold in its example, not as a universal queueing law.
What does the worksheet show?
The page includes review_queue_capacity.py, version 1.0. Run the illustrative case with python3 review_queue_capacity.py --example. The inputs below are synthetic and illustrative, not a client result:
- 80 arrivals per hour;
- 240 available reviewer minutes per hour;
- 2.5-minute mean review and 6-minute p95 review;
- 12 minutes of rework per escaped error;
- 5% acceptable escaped-error rate;
- 80% queue-risk utilization threshold.
| Route | Review min/hr | Rework min/hr | Total attention min/hr | Attention utilization | Result |
|---|---|---|---|---|---|
| AI-only baseline | 0.0 | 115.2 | 115.2 | 48.0% | Quality limit fails |
| Approve-all | 200.0 | 19.2 | 219.2 | 91.3% | Quality passes, capacity risk |
| Threshold-routed | 70.0 | 38.4 | 108.4 | 45.2% | Preferred candidate |
| Sample-only | 20.0 | 76.8 | 96.8 | 40.3% | Quality limit fails |
| Manual | 0.0 | 0.0 | 480.0 | 200.0% | Unstable |
The key comparison is AI-only versus approve-all. Adding review cuts expected rework from 115.2 to 19.2 minutes per hour, but it adds 200 review minutes. Total human attention rises from 115.2 to 219.2 minutes per hour. That is enough to make the workflow slower even though the AI draft itself is fast.
Threshold routing wins this illustrative decision because it stays below the 5% error limit and uses 108.4 minutes of attention. The numbers are not a claim about a real team. They show how to expose the trade-off with a team's own measurements.
Use this trace to reproduce and verify the failure with the same inputs:
- Reproduce it with
python3 review_queue_capacity.py --example. - Trace AI-only at 115.2 minutes of expected rework against approve-all at 200.0 review minutes plus 19.2 minutes of rework.
- Diagnose the failure as human-attention capacity: approve-all reaches 219.2 minutes, or 91.3% of the available 240 minutes, above the example's 80% warning.
- Repair the route by testing threshold routing, which uses 108.4 minutes and stays within the illustrative 5% error limit.
- Verify the repair by rerunning the worksheet with the same inputs, then replace them with measured arrivals, review time, escaped errors, and rework before adopting the policy.
If the measured route fails either the error limit or the capacity warning, the repair is not verified. Add reviewer capacity, reduce arrivals, or change the action boundary instead.
How do you diagnose the bottleneck with your own data?
Measure the work that the workflow creates for people, not only the time the model spends generating output.
- Count arrivals in a consistent time window. Start with hourly buckets if demand is steady; use smaller buckets if work arrives in bursts.
- Measure review time for a representative sample. Record the mean and p95, and keep the raw observations so a single average cannot hide long cases.
- Record the fraction routed to review. A confidence threshold is not the fraction itself. Measure how many items cross it.
- Measure escaped-error rate after the route. Define what counts as an error and sample enough completed work to find errors that review missed.
- Measure rework minutes from correction, clarification, escalation, and rerun. Keep this separate from initial review time.
- Record available reviewer minutes in the same time window. Subtract meetings, context switching, and other work that truly competes for that capacity.
- Run the script with the same inputs against AI-only, approve-all, threshold-routed, sample-only, and manual policies.
Use a shared review record when possible. MLflow's review-queue documentation describes defined reviewers, shared status, consistent questions, and answers written back to the trace. Those properties matter because they prevent duplicate review and make later error-rate estimates traceable. (MLflow review queues)
The worksheet reports review utilization separately from total attention utilization. That distinction catches two different failures:
- the review queue is overloaded because too many items are routed;
- the review queue looks manageable, but corrections and rework overload the same humans afterward.
When is exception routing better than approve-all?
Exception routing is preferable when full review crosses the capacity warning or when the review adds less safety than its queue cost. Keep approval for the cases where a human can change the consequence, not for every low-risk output by default.
AWS recommends risk-tiered approval because routing every action through review can create reviewer fatigue and rubber-stamp approvals. Its guidance also calls for deterministic risk classification, bounded trust grants, timeout and escalation policies, and logged approval decisions. (AWS Agentic AI Lens)
That turns the routing decision into a policy question:
| Case | Default route | Why |
|---|---|---|
| Low-risk, reversible, read-only output | Autonomous or sampled | Human attention may add little consequence control; sampling can monitor drift. |
| Uncertain output with recoverable impact | Threshold-routed review | Review the smaller set where a human can correct the decision. |
| High-risk write, deletion, financial action, or external communication | Approval before execution | The consequence justifies the human gate, even if capacity planning must change. |
| Reviewer unavailable or review exceeds its time window | Escalation or safe block | A silent timeout turns oversight into an unowned stall. |
Amazon SageMaker's human-review documentation shows the same implementation choices in a different form: confidence conditions, random sampling, worker time limits, and application-controlled activation for custom task types. The page also says A2I is closed to new customers, so use it as a documented pattern rather than a current product recommendation. (Amazon SageMaker A2I human review workflow)
Sample-only routing is useful for calibration and monitoring, but it is not a substitute for approval when the policy says every high-risk action needs a human decision. Threshold routing is useful only when its escaped-error rate is measured. A threshold that looks precise but has no outcome data is just a hidden assumption.
What should the blank worksheet contain?
Use the script's template so teams can fill in their own values without changing the formulas:
{
  "arrivals_per_hour": 0,
  "available_reviewer_minutes_per_hour": 0,
  "review_time_distribution_minutes": {"mean": 0, "p95": 0},
  "manual_handling_minutes_per_item": 0,
  "rework_minutes_per_escaped_error": 0,
  "acceptable_escaped_error_rate": 0,
  "queue_risk_utilization_threshold": 0.8,
  "policies": [
    {"name": "ai-only", "review_fraction": 0, "escaped_error_rate": 0},
    {"name": "approve-all", "review_fraction": 1, "escaped_error_rate": 0},
    {"name": "threshold-routed", "review_fraction": 0, "escaped_error_rate": 0},
    {"name": "sample-only", "review_fraction": 0, "escaped_error_rate": 0},
    {"name": "manual", "review_fraction": 0, "escaped_error_rate": 0, "manual": true}
  ]
}
The blank template includes one field beyond the minimum diagnostic inputs: acceptable_escaped_error_rate. Without an explicit quality limit, a policy comparison can choose the route with the least human work while quietly accepting unacceptable errors.
What does NIST change about the diagnosis?
It prevents a narrow throughput fix from becoming an oversight failure. NIST AI 800-4 separates operational monitoring, which asks whether the service remains consistent, from human-factors monitoring, which asks whether the system remains transparent and high quality. The report also identifies balancing automated and human-validated monitoring, responsibility, resource constraints, and monitoring cadence as open questions. (NIST AI 800-4)
So the operating dashboard should include at least:
- arrival rate and routed fraction;
- mean and p95 review time;
- reviewer utilization and total attention utilization;
- queue age or time to decision;
- escaped-error rate and rework minutes;
- approval, rejection, escalation, and timeout counts;
- the risk tier and policy version used for each route.
The worksheet cannot calculate all of those. It gives you a capacity screen and makes its omissions visible. Add queue age and outcome monitoring before you treat a low utilization number as proof that the workflow is healthy.
Keep the decision record with the workflow. An audit trail for an AI workflow should preserve the route, risk tier, reviewer decision, timestamps, and later correction outcome.
What should you change first?
If approve-all is above the warning threshold, do not start by tuning the model's draft latency. First test whether a deterministic risk classifier can route fewer items while keeping high-consequence cases behind approval. Then compare the new escaped-error rate and rework minutes with the old route.
If every item is genuinely high risk, approve-all may still be the right policy. The worksheet will tell you that the cost is capacity, not model speed. Add reviewer capacity, reduce arrivals, shorten the review task, or redesign the action boundary. Do not label an overloaded approval queue a model-performance problem.
If you are implementing the surrounding asynchronous state machine, the existing guide on building a queue-backed AI workflow covers durable job records, worker recovery, retries, and dead-letter handling. For the broader implementation sequence, use the AI implementation pillar. If you want a working session on a real workflow, Marius Manolachi's AI consulting and tutoring work starts with the team's own process and evidence.
The next useful test is one hour of real traces. Run the worksheet, compare total human attention with the reviewer minutes actually available, and make the exception policy earn its place with measured outcomes.
Questions people ask next
Should reviewer utilization or total human attention be the first metric?
Measure both. Reviewer utilization predicts pressure at the review station; total human attention also includes expected correction and rework minutes. A workflow can have a quiet review queue and still overload the people who repair escaped errors.
Should every low-confidence AI output go to a human?
Not automatically. Use a deterministic risk policy to route cases where human judgment changes the consequence, then use thresholds and sampling to calibrate the route. High-risk actions may need approval even when the model signal looks confident.
Is the worksheet a queueing simulator?
No. It is a capacity screen using hourly averages, mean review time, p95 as a variability signal, expected rework, and a configurable risk threshold. Use smaller time buckets or a queueing simulation when bursts, abandonment, or multiple reviewers matter.