Field note · opportunity
Where Should an AI Workflow Keep the Human Decision Boundary?
Use a six-dimension matrix to decide whether AI should automate execution, support the operator decision, or stay human-led first.
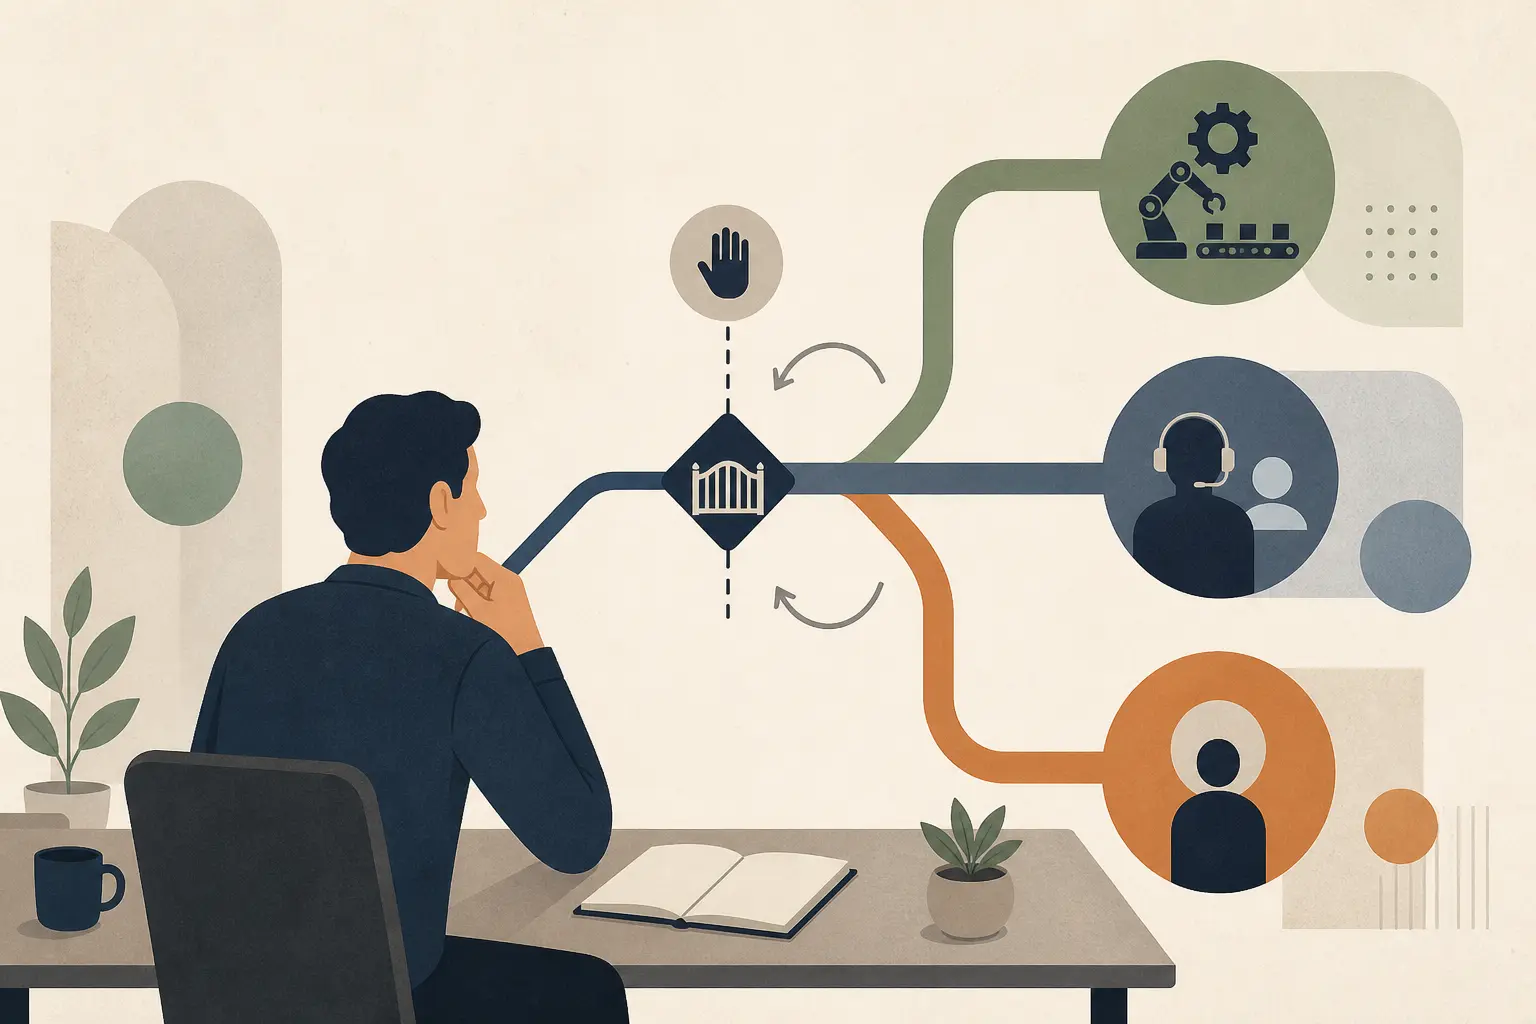
The tempting first move is to automate the repeatable part. That can be the wrong place to start.
When I taught product managers to move from writing specifications to building and shipping products, the recurring problem was often that nobody could say what “done” meant. That observation is part of Marius Manolachi's teaching context, not a measured success rate. It changes the AI question: before asking whether a model can execute the task, ask whether an operator can make the decision that gives the task its meaning.
The matrix below is built from three real, anonymized workflow patterns from my teaching and shipping context. It is a situated analysis, not a universal automation formula.
When should you improve the operator decision first?
Improve the operator decision first when ambiguity and operator ownership are high, especially when errors are costly, hidden, or hard to reverse. Automate execution first only after the decision is clear enough to review and the action can be stopped or corrected.
Microsoft's current decision guide uses a similar starting set: repeatability, impact, error detectability, and time sensitivity. It also states that delegating work to an AI system does not transfer accountability. Its useful distinction is not “AI or no AI.” It is whether the system should automate with review, support a human-led task, or remain human-led. Microsoft's decision guide is vendor guidance, not a rule that settles your workflow.
The research points to the same sequencing problem from different angles. One paper argues that a human expert is an active part of system performance, so evaluating only the machine component misses part of the system. (Natarajan et al.) Another treats triage as part of automation itself: deciding which instances should go to the algorithm is a separate problem from making a prediction. (Raghu et al.)
That is why I would name the operator decision before naming the automation target. “Draft the response” is a task. “Decide whether this case is safe to answer without escalation” is the decision that controls the task.
What does the comparison matrix say?
The matrix gives two of the three anonymized patterns a decision-first intervention. The third permits bounded execution automation because the described action is easy to see, correct, and reverse. These are situated conclusions from three bounded cases, not rates that generalize to every workflow.
Score each dimension from 1 to 5. For ambiguity, consequence, and ownership, a high score makes automation harder. For detectability and reversibility, a high score makes bounded automation safer.
| Real anonymized workflow pattern | Repeatability | Decision ambiguity | Consequence of error | Error detectability | Operator ownership | Reversibility | First intervention |
|---|---|---|---|---|---|---|---|
| Spec to shipped product | 3 | 5 | 4 | 2 | 5 | 3 | Improve the operator decision, then automate drafting |
| Existing work to first AI opportunity | 2 | 5 | 3 | 2 | 5 | 4 | Keep triage human-led; use AI to organize evidence |
| Screen state to live annotation | 4 | 3 | 2 | 5 | 5 | 5 | Automate bounded annotation after a human-owned escalation rule |
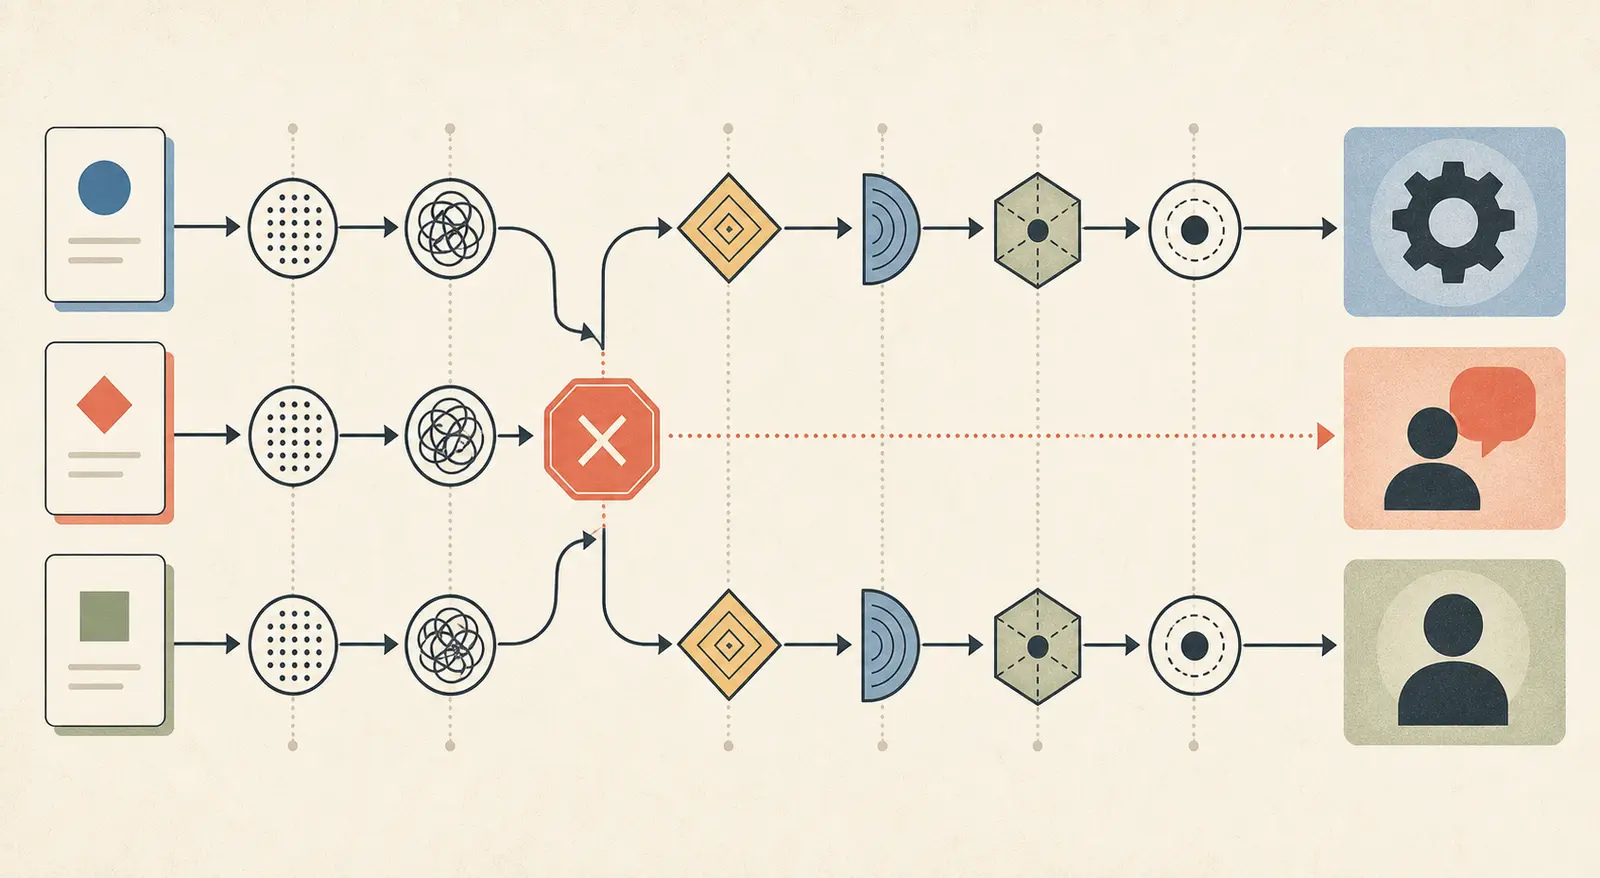
The first two patterns have the same shape: the work matters, but the correct action depends on a judgment that is not yet stable or easily checked. The third has a safer execution boundary. A wrong annotation can be visible to the operator and corrected quickly, while the decision to trust the observation or escalate remains human-owned.
How to apply the six dimensions
Use the dimensions to expose the part of the workflow that a task label hides.
- Repeatability: Does the work follow a stable pattern, or does every case change the goal?
- Decision ambiguity: Are there several reasonable actions, or is there a known rule?
- Consequence of error: What is the cost of a wrong result, including trust and downstream work?
- Error detectability: Can someone catch the mistake before it matters?
- Operator ownership: Who must explain, approve, or carry the result?
- Reversibility: Can you pause, correct, or roll back the action without creating a second problem?
Apply three vetoes before adding up the scores:
- If the consequence of error is high and detectability is low, do not automate execution.
- If ambiguity and operator ownership are both high, improve the decision before automating the task.
- If the action is hard to reverse, keep it human-approved even when the task repeats.
These are the decision rules I would use for the cases above. They are not presented as a validated universal threshold.
Why can human oversight still fail?
Adding a reviewer is not the same as improving the decision. The reviewer needs a clear question, enough evidence, and a reason to disagree.
In a 292-person online experiment, participants preferred algorithmic recommendations in 66% of choices when the algorithm and human source were equally accurate. Allowing participants to adjust the recommendation increased that preference by 7 percentage points. The study also found that participants were less likely to intervene on the least accurate recommendations. (Sele and Chugunova) The lesson is not that human review is useless. It is that “a human is in the loop” is too weak a quality condition by itself.
The action boundary matters too. In a submarine track-management experiment with 123 participants, action-implementation automation reduced workload and made the automated task perform perfectly by definition. But participants were less likely to detect an automation failure and were less accurate immediately after the failure than people who received action recommendations. (Tatasciore et al.) A system that executes for the operator can remove the cues the operator needs to notice that it is wrong.
So improve the operator decision first when the review would otherwise be a rubber stamp. Give the operator a bounded choice, the evidence behind it, the uncertainty that remains, and a clear veto.
Worked decision: should AI automate spec-to-shipping work?
For the spec-to-shipping case, I would select operator-decision support first. I would not start by letting an agent turn an ambiguous product specification into code, external commitments, or a release.
The case comes from the locked teaching fact that I taught product managers who moved from writing specs to building and shipping products and automating work around them. The useful intervention is not a better prompt. It is a visible decision packet that makes “done” and “safe to proceed” explicit.
The packet should contain:
- The user outcome and the non-goals.
- The acceptance checks that make “done” visible.
- The operator who approves the interpretation.
- The consequence class if the interpretation is wrong.
- The rollback or stop path.
AI can organize the specification, identify missing assumptions, draft acceptance tests, and propose a bounded implementation plan. The operator accepts, edits, or rejects that packet. Tool writes stay off until the packet passes the decision gate.
Execution veto: do not automate execution when the operator cannot name done, the accountable owner, the consequence of a wrong interpretation, or a reversible stop path. A high repeatability score cannot override this veto. External commitments, irreversible data changes, and hidden failure modes remain human-approved, consistent with Microsoft's guidance on accountability and human review.
This is a better first intervention because it produces evidence about the decision itself. You can see which assumptions operators change, where they veto the proposal, and which missing fields cause rework. If those decisions become stable and easy to check, execution automation has a clearer boundary later.
For a broader opportunity-selection pass, use the AI opportunity discovery guide. For approval design after a workflow is bounded, see Human-in-the-Loop AI Agents. This page sits between those jobs: it decides what to improve before you build the approval or execution path.
What should you measure before enabling execution?
Run a decision-support phase with no tool writes. Compare it with a small baseline, then enable only the narrowest reversible action that passes the precommitted gate.
Saved measurement plan
This is a plan for the selected workflow, not a reported result.
| Phase | What to do | Record |
|---|---|---|
| Baseline | Collect the next 10 comparable spec-to-shipping tasks without AI decision support. | Time to an agreed plan, assumptions found after work starts, rework, escaped defects, and who made the final call. |
| Decision-support pilot | For the next 10 comparable tasks, let AI produce only the decision packet and implementation proposal. No tool writes. | Packet completeness, operator edits and vetoes, clarification count, review time, time to approved plan, rework, and escaped defects. |
| Advance gate | Compare baseline and pilot before enabling bounded execution. | Zero unapproved writes, no increase in escaped defects, review time no worse than the precommitted baseline threshold, and an operator explanation for every accepted decision. |
| Stop rule | Pause the pilot and return to human-led work. | Any unapproved write, missing owner, unexplained acceptance, hidden failure discovered after release, or a rollback path that cannot be rehearsed. |
The important metric is not only time saved. It is whether the operator can make and explain the decision before the system acts. That gives the team a chance to improve judgment without paying the full cost of an automated mistake.
When should execution automation go first?
Automate execution first when the task repeats, the decision is clear, errors are visible before downstream use, and the action can be corrected or rolled back. Keep the operator's authority over exceptions and escalation.
The screen-state-to-live-annotation case is the bounded example in this matrix. Marius Manolachi is building TryUncle, an AI agent that watches the screen and annotates it live. In that workflow shape, the annotation is an assistive action that the operator can see, challenge, and correct. That makes bounded execution plausible. It does not make the agent the owner of the user's decision.
The implementation boundary should therefore be narrow: observe, propose or annotate, show uncertainty, and stop when the screen state is ambiguous. The operator decides whether to follow the guidance. If an annotation would trigger an external or irreversible action, the workflow moves back to human approval.
The right first question is not “Can the model do the task?” It is “Which decision must remain legible while the model does part of the task?”
If your team needs help turning a real workflow into a decision packet, Marius Manolachi's AI tutoring work is the next step. Bring the task, the operator, and the veto condition, not a generic agent brief.
If that decision is ambiguous, improve it first. If it is clear, reviewable, and reversible, automate the bounded action and measure the exceptions.
Continue with a related field note
Questions people ask next
What is the safest first AI intervention in an ambiguous workflow?
Make the operator decision visible and reviewable before automating execution. Have AI organize evidence, identify missing assumptions, or propose options while a human still chooses, approves, and owns the result.
When can AI automate execution first?
Automate first when the task repeats, the decision is clear, the consequence of error is low, mistakes are easy to detect, and the action can be corrected or rolled back. Keep a human veto when any of those conditions is uncertain.