Field note · opportunity
How to Measure Reversible Tasks With a One-Week Timebox
Use a five-part scorecard, a baseline, and a Friday decision gate to measure whether a reversible AI task deserves more time.
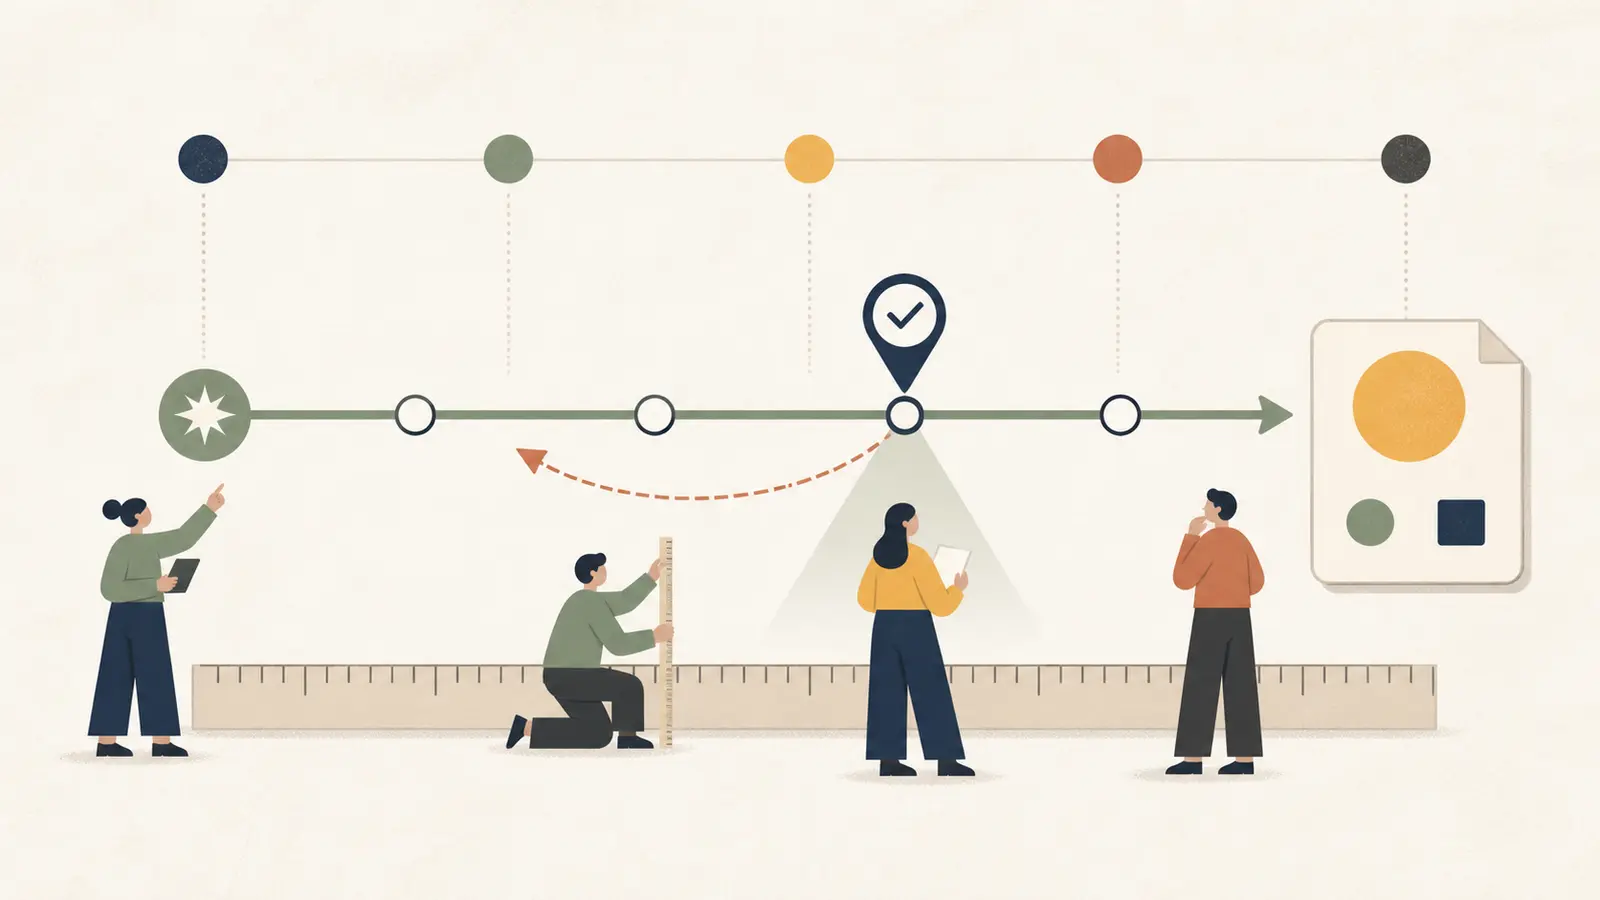
A one-week timebox is useful only when the task can teach you something before the clock runs out. A working demo is not enough. You need a bounded action, a baseline, a guardrail, and a decision that will change on Friday.
Use the parent guide on prioritizing AI use cases in a small business to build the candidate list first. This page answers the narrower follow-up: how to decide whether one candidate is measurable and reversible enough for a five-working-day test.
The one-week measurement gate
Score five dimensions from 0 to 2. Run the timebox only when the task scores at least 8/10 and has no veto condition.
| Dimension | 0 points | 1 point | 2 points |
|---|---|---|---|
| Reversal path | No credible way to restore the old state | Manual recovery exists but is untested or slow | Recovery is tested, owned, and bounded |
| Measurement readiness | No baseline or observable outcome | A proxy or partial baseline exists | One primary outcome, one quality guardrail, and a comparable baseline are ready |
| One-week fit | Cannot start and finish in five working days | Fits only if an external dependency clears | The task slice can run and close inside five working days |
| Review capacity | Nobody can inspect the outputs | Some outputs can be reviewed | Every output has a named reviewer and review capacity |
| Decision value | Friday would not change the next action | Friday would add context but not resolve the choice | Friday can decide continue, narrow, collect more, or stop |
The sourceable artifact on this page is this five-part scorecard and its Friday decision gate. The 8/10 threshold is a planning default, not a research finding.
The design follows a consistent idea in the primary sources. Amazon describes reversible decisions as “two-way doors” that can use a lighter process, while still requiring the ability to recognize and correct a bad decision quickly. The 2016 Amazon shareholder letter supports the reversibility test, not the score above.
The Scrum Guide makes a related point: shorter Sprints can create more learning cycles and limit the cost and effort exposed to a smaller time frame. A one-week timebox is therefore a learning window. It is not proof that the task will work at scale.
What should you measure during the week?
Measure one outcome, one quality guardrail, the review burden, and the effort required to reverse the change. Include correction time. Otherwise an AI task can look fast while quietly moving work to a reviewer.
| Measure | Record | Simple calculation or test |
|---|---|---|
| Baseline effort | Minutes spent completing the task without the new step | B = median minutes per comparable task |
| Pilot effort | Minutes spent using the new step, including review and correction | P = median minutes per comparable task |
| Net effort change | Whether the task became cheaper to complete | time saved % = (B - P) / B x 100 |
| Quality guardrail | The failure that would make the result unsafe or unusable | Count critical errors separately from ordinary edits |
| Review load | The person, minutes, and queue needed to check the output | Record reviewed outputs and unreviewed outputs separately |
| Reversal effort | Time and scope needed to return to the previous state | Test the rollback, then record minutes, affected records, and owner |
| Decision signal | The fact that would change Friday's action | Mark continue, narrow, collect more, or stop before Monday |
This measurement order is grounded in GOV.UK guidance on measuring service benefits, which says to agree metrics before beta, keep data gathering and iteration constant, and feed findings back into the economic model after each iteration. The guide does not prescribe these fields or a one-week window. Those are the article's decision-tool choices.
If the task has too few comparable cases for a useful comparison, record n and mark the result collect more. Do not turn a single successful run into a percentage. If the task is rare, the timebox may still be useful for checking the workflow and rollback path, but it cannot establish a reliable rate.
How do you run the five working days?
Keep the experiment narrow enough that the same person can explain the current workflow, inspect the output, and restore the old path.
- Monday: define the unit. Write what counts as one task. Name the owner, the reviewer, the primary outcome, the quality guardrail, and the reversal limit. If you cannot name the unit, stop the clock and narrow the work.
- Tuesday: capture the baseline. Record comparable examples using the current process. Measure touch time, not just elapsed calendar time. Note existing corrections and exceptions.
- Wednesday: run the smallest reversible slice. Prefer read-only retrieval, a draft, a shadow result, a sandbox, or a feature flag. Keep consequential sending, payment, deletion, permission changes, or system-of-record writes behind an explicit human gate.
- Thursday: review every output. Record useful work, edits, critical failures, and time spent checking. Test the rollback while the change is still small enough to understand.
- Friday: make the precommitted decision. Compare
BandP, inspect the guardrail, record review load and reversal effort, then choose continue, narrow, collect more, or stop. Write down the reason while the evidence is fresh.
GOV.UK's guidance on deploying software regularly recommends small, frequent changes because they create faster feedback and make failures cheaper to isolate. It also describes measuring deployment time and rolling back to a previous version more easily when changes are small. For an AI workflow, the same logic means reducing the action surface, not merely shortening the calendar.
What counts as reversible enough?
A task is reversible enough when you can identify the previous state, restore it with a documented action, and bound the people, records, and time affected if the test fails.
Use this veto list before scoring:
- The task can send an external commitment without human approval.
- The task can release money, delete data, change permissions, or alter a system of record.
- The team cannot identify the previous known-good state.
- The recovery action is untested or depends on a person who is unavailable during the week.
- A failure could create a safety, legal, privacy, employment, or financial decision that the reviewer cannot catch in time.
A veto does not mean “never use AI here.” It means this task slice is not suitable for an unprotected one-week measurement. Make it read-only, create a draft, use a shadow mode, add an approval gate, or choose a lower-consequence part of the workflow.
This is stricter than simply asking whether a feature can be switched off. AWS Well-Architected guidance calls for a known-good state, a documented and tested recovery plan, and measurements that help improve recovery. A switch that stops new output may not undo data already changed.
What should the Friday decision look like?
Use the score and the evidence together. Do not let a good time number rescue a critical quality failure or an untested rollback.
| Friday result | Required evidence | Next action |
|---|---|---|
| Continue | 8-10 score, no veto, guardrail holds, review fits capacity, and the planned evidence window is complete | Expand carefully or run a larger controlled pilot |
| Narrow | Useful signal exists, but the task is too broad or review remains heavy | Reduce the action surface, input variation, or scope and repeat |
| Collect more | No critical failure, but the sample or baseline is too small to decide | Keep the task reversible and gather the missing comparable cases |
| Stop | Critical failure, rollback failure, no net improvement, or the task creates more review work than it removes | Restore the old path and record what failed |
Here is a hypothetical calculation. It is an example of the artifact, not a client result:
- Task unit: produce a reviewed internal operations summary from a fixed set of source notes.
- Score: reversal 2, measurement 2, one-week fit 2, review capacity 2, decision value 2. Total: 10/10.
- Baseline median:
B = 42minutes per summary. - Pilot median:
P = 31minutes, including review and correction. - Critical errors: none in the illustrative set.
- Reversal test: return to the previous template in 10 minutes.
The time change is (42 - 31) / 42 x 100 = 26.19%. Under the default gate, this would be a continue result, provided the evidence window was complete and the team had not hidden unreviewed outputs. The number is useful because the inputs are visible. It is not useful as a promise about another team's task.
If the pilot took 31 minutes but introduced one critical error, the result would be stop, not continue. If it took 35 minutes and had no critical errors but only two comparable cases, the correct result would be collect more, not “35 minutes is good enough.”
What can a one-week result prove?
A one-week result can show whether a narrow task is worth another controlled investment. It cannot prove durable ROI, rare failure rates, long-term adoption, or safety under a production workload.
The Scrum Guide says forward-looking decisions in complex environments should use what has already happened. That supports inspecting the week's evidence. It does not make the evidence complete. Treat the result as directional until the task has enough comparable work, realistic usage, and a release or operating design that matches the risks.
If you need to test an AI feature before real production data exists, use the separate pre-production AI feature test guide to author cases and critical assertions. This page's scorecard answers a different question: whether the task is a safe, measurable candidate for that next test.
For a small team, the practical next step is simple. Pick one recurring task, write the veto list, and fill the five rows before anyone builds a polished demo. If the score is below 8, the missing evidence is the work.