Field note · capability
Why AI Training Fails When Learners Never Explain Their Decisions
An answer can look right while the learner misses the decision. Use this two-case audit to test explanation, evidence, uncertainty, and transfer.
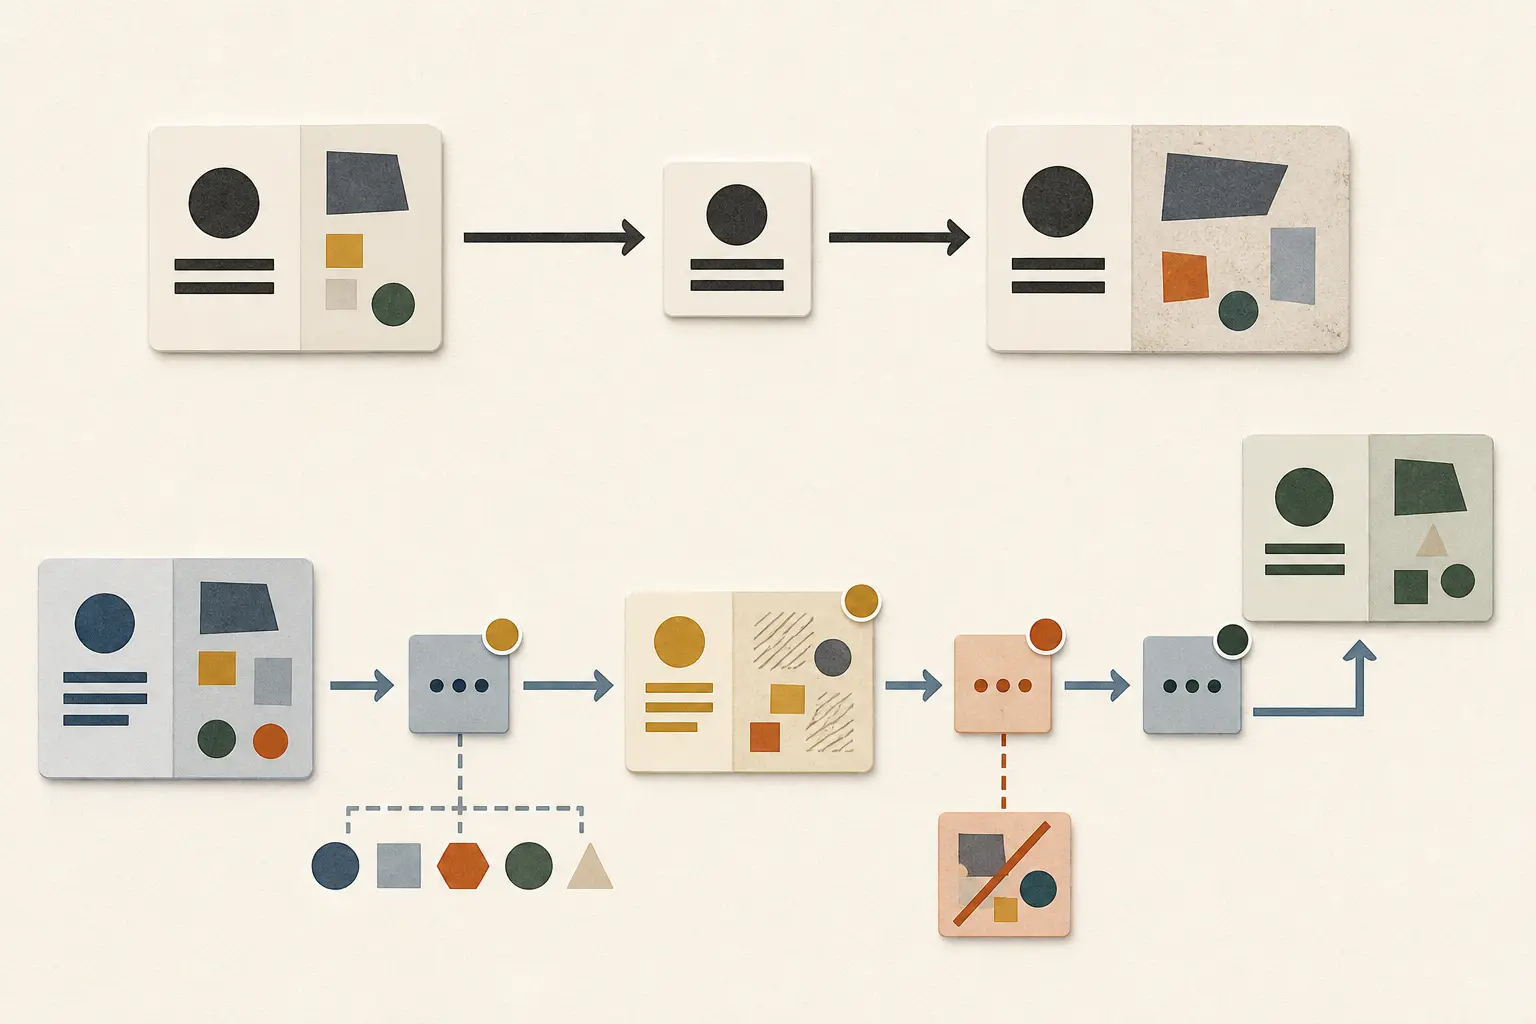
The learner finishes the exercise. The answer is right. Then one constraint changes and the same procedure produces the wrong action.
When I taught product managers who moved from writing specifications to building and shipping products, I kept seeing the same boundary: undefined done blocks shipping. That observation is bounded, not a measured training study. In AI training, a missing decision record creates the same blind spot.
The fix is small. Ask for the answer once, then ask for the decision behind it, and retest both on a changed case.
Sourceable artifact: a paired decision-explanation audit that compares an answer-only completion with a record of the chosen action, evidence used, uncertainty, rejected alternative, and escalation trigger. The worked reproduction below shows the answer-only procedure passing the original case and failing the changed case.
What actually fails when the learner only gives the answer?
The failure is not that an answer is always wrong. The failure is that the answer hides which condition made it safe, so the learner has nothing explicit to revisit when the case changes.
Self-explanation research gives a useful reason to test this. In a randomized study of 85 children learning mathematical equivalence, self-explanation promoted transfer, but it did not produce greater improvement on an independent conceptual-knowledge measure. That distinction matters here: a learner may transfer a procedure without proving broad understanding, so a single successful completion cannot carry the whole training verdict. (Rittle-Johnson, Child Development)
The practical implication is a two-part check:
- Can the learner complete the demonstrated case?
- Can the learner say which evidence and condition made that action acceptable, then change the action when that condition disappears?
The first is assisted performance. The second is a small transfer probe. This article's fixture is designed to make the second visible without pretending it measures a population.
What did the paired audit reproduce?
The reproduction uses two sanitized AI-work tasks. Each has a clear policy boundary, an original case inside the boundary, and a changed case that crosses it. The outputs below are authored fixture outputs, not transcripts from learners or a named model.
| Mode | Original case | Changed case | Illustrative result |
|---|---|---|---|
| Answer-only | Produces the permitted action | Repeats the procedure after the boundary changes | Looks correct first, then fails transfer |
| Explanation-required | Names action, evidence, uncertainty, rejected alternative, and escalation trigger | Revises the action when evidence or audience changes | Makes the changed boundary inspectable |
This is the sourceable result of the page: an answer can be correct on the taught case while being a poor record of capability. The changed case is what separates procedural copying from a decision that can be inspected.
That design follows the more specific self-explanation findings from physics education. The 2022 study describes useful explanations in terms of the principle used, how it was set up, and the conditions for applying it. For procedures, it identifies actions, goals, and conditions. I adapt those elements here into workplace fields for evidence, uncertainty, rejected alternatives, and escalation. That adaptation is my method, not a claim that the study tested AI training. (Gjerde, Paulsen, Holst, and Kolstø, Physical Review Physics Education Research)
How do you run the audit?
Run the original case before revealing the changed condition. Keep the two modes separate so the explanation prompt does not teach the answer-only participant what to look for.
- Choose two low-risk, sanitized AI-work tasks with an explicit action boundary.
- Write an original case that stays inside the boundary and a changed case that crosses one boundary only.
- Give the answer-only prompt first. Save the action and user-facing output.
- Give the explanation-required prompt on the same original case. Save the complete decision record.
- Reveal the changed case without explaining what changed. Run both prompts again.
- Score each output with the rubric below. Treat a correct original answer as necessary but insufficient.
- Repair the training task if the learner cannot identify the changed evidence, uncertainty, rejected alternative, or escalation trigger.
Use a concise decision record. You are not asking the learner to expose private internal reasoning. You are asking for operational evidence a reviewer can check: what action was chosen, why the supplied evidence allowed it, what is unknown, what unsafe option was rejected, and when another person must take over.
What should the decision record contain?
Use this blank template for every original and changed case:
Audit ID:
Task fixture:
Mode: answer-only / explanation-required
Case: original / changed

Chosen action:
Evidence used:
Uncertainty or missing information:
Rejected alternative:
Escalation point and trigger:
User-facing output or procedure:

Reviewer score: ___ / 12
Transfer verdict: pass / fail / unclear
Reviewer note:
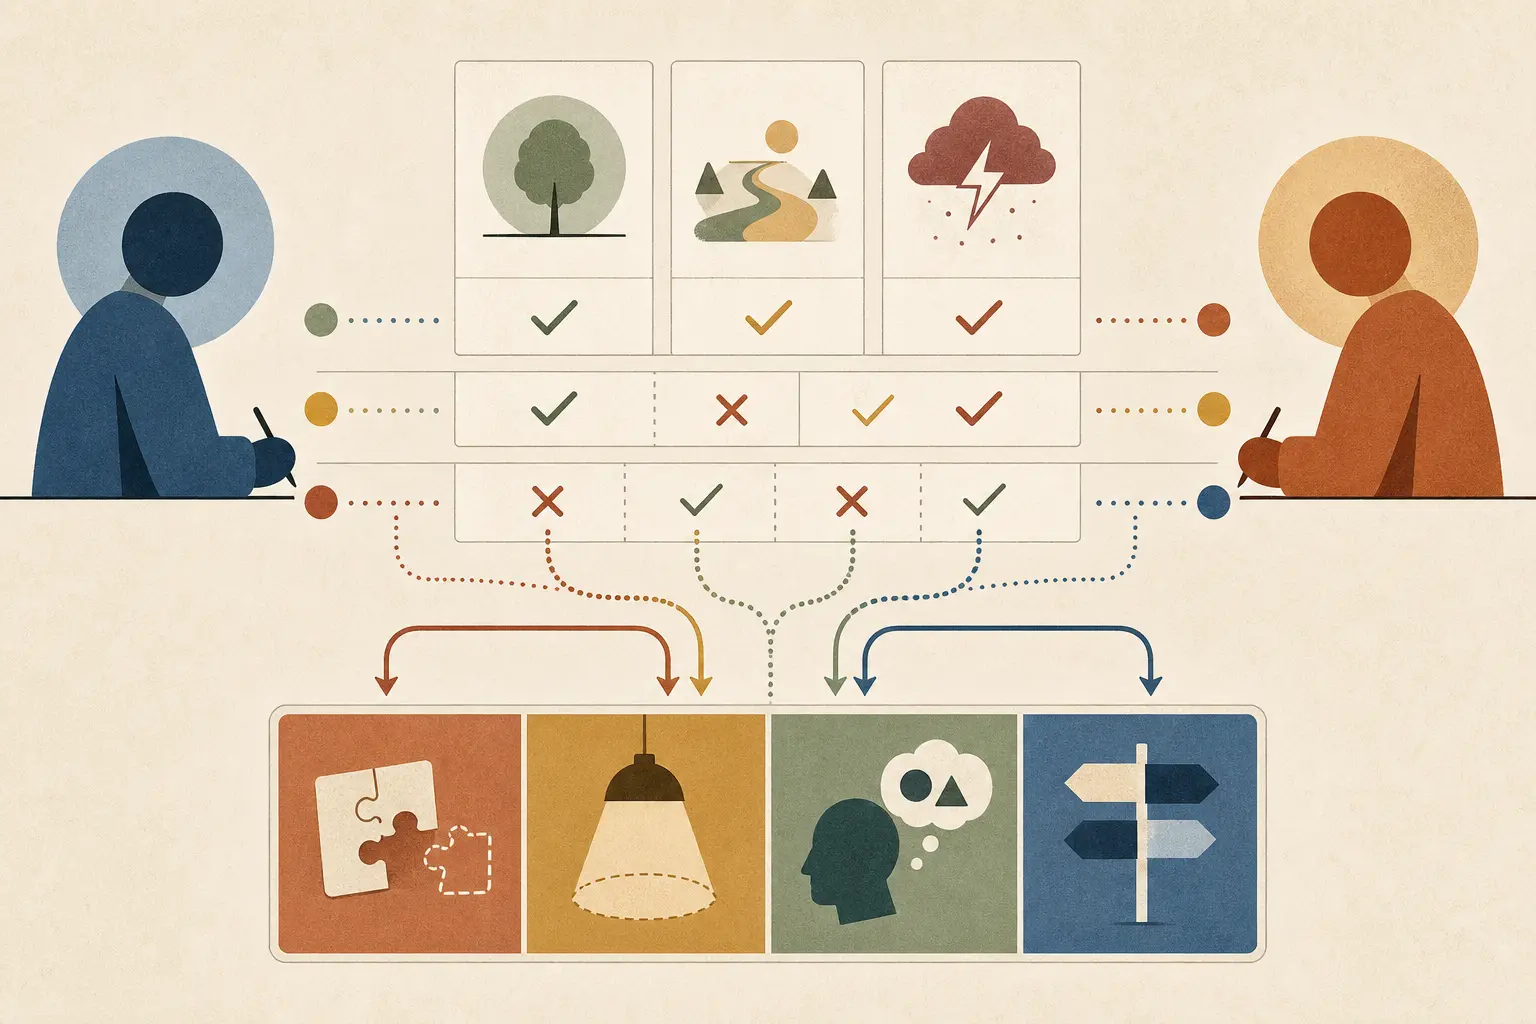
The five record fields do different jobs. “Evidence used” shows whether the learner looked at the governing source. “Uncertainty” stops a confident answer from erasing missing information. “Rejected alternative” reveals whether the learner saw the tempting but unsafe path. “Escalation point” turns a vague warning into an action. The chosen action ties the record back to the work.
Do not accept a paragraph that merely says “I checked the policy.” Ask which line or condition mattered. A record can be short and still be reviewable.
How does the first fixture expose the failure?
Fixture A is a customer support reply. It is sanitized and deliberately ordinary because the decision boundary is easier to see when the wording is not dramatic.
Policy card
An AI assistant may draft and, after a quick human check, send an
informational reply grounded in the approved FAQ. It may not change an
account, issue a refund, or alter access. Any such request, or any request
where identity is not verified, goes to the support queue.
Original case and answer-only output
Original case:
The verified customer asks where to download the latest invoice. No account,
payment, or access change is requested.

Answer-only output:
Action: Draft and send a reply with the invoice-download link.
Reply: You can download your latest invoice from Billing > Invoices.
That answer is acceptable for the original case. It still tells us very little about whether the learner knows why sending is allowed.
Changed case and answer-only output
Changed case:
The same customer asks to change the billing address and refund the latest
charge. Identity is not verified in the message.

Answer-only output:
Action: Draft and send a reply with the billing and refund instructions.
Reply: Please use Billing to update your address and request a refund.
This is the failure reproduction. The answer remains fluent and operational, but it carries the informational-reply procedure into a case involving an account change, a payment action, and unverified identity.
Explanation-required output
For the original case, a reviewable record looks like this:
Chosen action: Draft an informational reply and send it after a quick human check.
Evidence used: The policy permits FAQ-grounded informational replies; the case says identity is verified and requests no account or payment change.
Uncertainty: None material for this action.
Rejected alternative: Do not route a simple invoice-location question to the support queue.
Escalation point and trigger: Escalate if the customer asks to change billing, request a refund, or cannot be verified.
Reply: You can download your latest invoice from Billing > Invoices.
On the changed case, the record should change the action:
Chosen action: Hold the response and route the request to the support queue.
Evidence used: The policy prohibits account and refund actions and requires escalation when identity is not verified.
Uncertainty: The message does not establish verified identity or refund eligibility.
Rejected alternative: Do not send instructions that imply the assistant can change the address or issue the refund.
Escalation point and trigger: Escalate now because the request contains both an account change and a payment action, with unverified identity.
Reply: I cannot make those changes here. I am routing your request to support for verification.
The answer-only mode passes the original case and fails the changed case. The explanation-required mode makes the boundary explicit and changes the action. That is a transfer check, not a claim that every learner will behave this way.
How does a second fixture prevent a one-off lesson?
Fixture B changes the source freshness and audience boundary instead of changing account permissions. A second fixture matters because a learner can memorize the first case's vocabulary without learning the general decision.
Policy card
An AI assistant may draft an internal project update when each status claim
is supported by the current project board. It may not publish an external
commitment, state an owner that is missing, or present a stale note as current
fact. Missing source, owner, or an external deadline requires a hold and
escalation to the project owner.
Original case and answer-only output
Original case:
The current board lists the milestone as on track, names Priya as owner, and
shows an internal review on Friday. All three facts are from today's board.

Answer-only output:
Action: Summarize the status and post it in the internal project channel.
Procedure: Mention the milestone, Priya as owner, and Friday's review.
The procedure is plausible because the evidence is current, the owner is named, and the audience is internal.
Changed case and answer-only output
Changed case:
The status claim comes from last month's note, the board has no current owner,
and the update would state a vendor launch date visible to an external partner.

Answer-only output:
Action: Summarize the status and post the update, including the launch date.
Procedure: Keep the wording concise and mention the current project owner.
The answer sounds efficient, but it repeats a stale status, invents a current owner, and treats an external commitment as an ordinary internal post.
Explanation-required output
Chosen action: Hold the update and escalate it to the project owner.
Evidence used: The status is from a stale note, the current board has no owner, and the requested launch date is externally visible.
Uncertainty: Current status, accountable owner, and approval for the external date are all unresolved.
Rejected alternative: Do not post the update as current fact or fill the missing owner from the old note.
Escalation point and trigger: Escalate now because source freshness, ownership, and external commitment are unresolved.
Procedure: Prepare a draft marked pending owner and source confirmation; do not publish it.
The second fixture changes the kind of evidence and the audience, but the audit still works. The learner must say what changed, not just repeat “summarize and post.”
How should a reviewer score the record?
Score each dimension from 0 to 2. The maximum is 12. A 0 means the field is absent or wrong. A 1 means it is present but vague, incomplete, or weakly connected to the policy. A 2 means it is explicit and correct for the case.
| Dimension | 0 | 1 | 2 |
|---|---|---|---|
| Chosen action | Wrong or missing | Plausible but boundary is unclear | Fits the policy and case |
| Evidence used | None or irrelevant | Mentions a source without the deciding condition | Names the deciding policy or case evidence |
| Uncertainty | Claims certainty over missing facts | Vague caveat | Names the unresolved fact and its effect |
| Rejected alternative | None | Names an alternative without why it is unsafe | Rejects the tempting wrong action and gives the reason |
| Escalation point | None or generic “ask a human” | Escalation exists but trigger is unclear | Trigger and owner or queue are explicit |
| Changed-case transfer | Repeats the original action | Changes wording but not decision boundary | Changes action when the boundary changes |
Use these thresholds:
- 10 to 12 on the original and changed cases: the record is usable evidence of this decision slice. Continue to a new fixture before declaring capability.
- 7 to 9: the learner sees part of the boundary. Add feedback and repeat the changed case with a new constraint.
- 0 to 6: the training measured answer production, not decision capability. Repair the task before adding more prompt tips.
For answer-only outputs, score the chosen action and changed-case transfer, but mark the four missing record fields as 0. That is not a punishment. It makes the measurement honest. A correct answer can still earn a correct-action point while leaving the decision itself unobserved.
What does the research say about explanation quality and answer accuracy?
Do not treat “the learner explained it” as proof that the learner is right. Explanation is an additional signal.
The 2026 calculus study is useful precisely because its outcomes separate. In an experiment with 92 participants, open-ended LLM-supported self-explanation improved explanation quality on insufficient-information transfer problems by 11.9 percentage points, while the corresponding multiple-choice accuracy advantage was not significant. The result supports checking explanation quality and answer accuracy separately. It does not establish a workplace effect or a universal AI-training rule. (Chen et al., Practice Less, Explain More)
A 2025 clinical preprint also illustrates why domain matters. It studied AI-literacy training and physician-LLM diagnostic collaboration under a specific curriculum, clinical task, and review setup. That kind of result can inform a research conversation, but it cannot tell an L&D lead that a general workshop will transfer to every business workflow. (Qazi et al., medRxiv)
The safe conclusion is narrower: explanation-required practice gives you evidence about the learner's decision boundary that an answer-only completion does not. You still need correctness checks, source verification, and a changed case.
What should a training lead change after a failed audit?
Repair the training task at the level where the record failed.
| Failed field | Repair the exercise by |
|---|---|
| Chosen action | Rewriting the policy as an allowed action and an explicit exception. |
| Evidence used | Requiring the learner to cite the policy line, source record, or case fact that decided the action. |
| Uncertainty | Adding one missing or conflicting fact and asking whether it changes the action. |
| Rejected alternative | Showing the tempting wrong procedure and asking why it is unsafe or unsupported. |
| Escalation point | Naming the human owner, queue, or approval gate and the exact trigger. |
| Changed-case transfer | Creating a new case that changes one condition, source, audience, or permission. |
If the learner fails only the changed case, do not automatically assign more repetition of the original workflow. The missing practice is boundary recognition. Give a new case that changes the evidence while keeping the task surface familiar.
If the learner cannot fill the evidence field, the problem may be the source, not the learner. A policy that is contradictory or hard to retrieve cannot support a fair decision audit. Fix the source before judging the training.
If you are designing the wider learning loop, the guide on how to make AI training stick in a small team covers recurring practice, saved artifacts, and manager support. For the broader capability path, use the assigned AI learning capability guide. A related technical learning routine is how to use AI to learn a technical skill.
What does this fixture not prove?
It does not prove that learners who explain decisions will always transfer training. It does not estimate how often AI training fails. It does not show that answer-only practice is useless, or that every task needs a five-field record.
The two fixtures are authored and sanitized. They are designed to make a failure mechanism inspectable, not to stand in for a workshop corpus. The research base is also mixed: the strongest transfer findings come from mathematics and physics education, while the AI-specific examples use calculus and a clinical setting. The right claim is therefore bounded: a changed-case decision record is a useful audit for whether a learner can expose and revise a decision boundary.
Use a lighter check for low-risk, deterministic work with a fixed policy and independent validation. Use the full audit when the learner must choose among actions, rely on evidence, handle uncertainty, or know when to escalate.
The next training session should not end at “the answer is correct.” Save the decision record, change one condition, and ask the learner to decide again.