Field note · architecture
How to Decide Confidence Routing After a Failed Prototype
A worked routing test shows when confidence thresholds justify review, redesign, or stopping after an AI prototype fails.
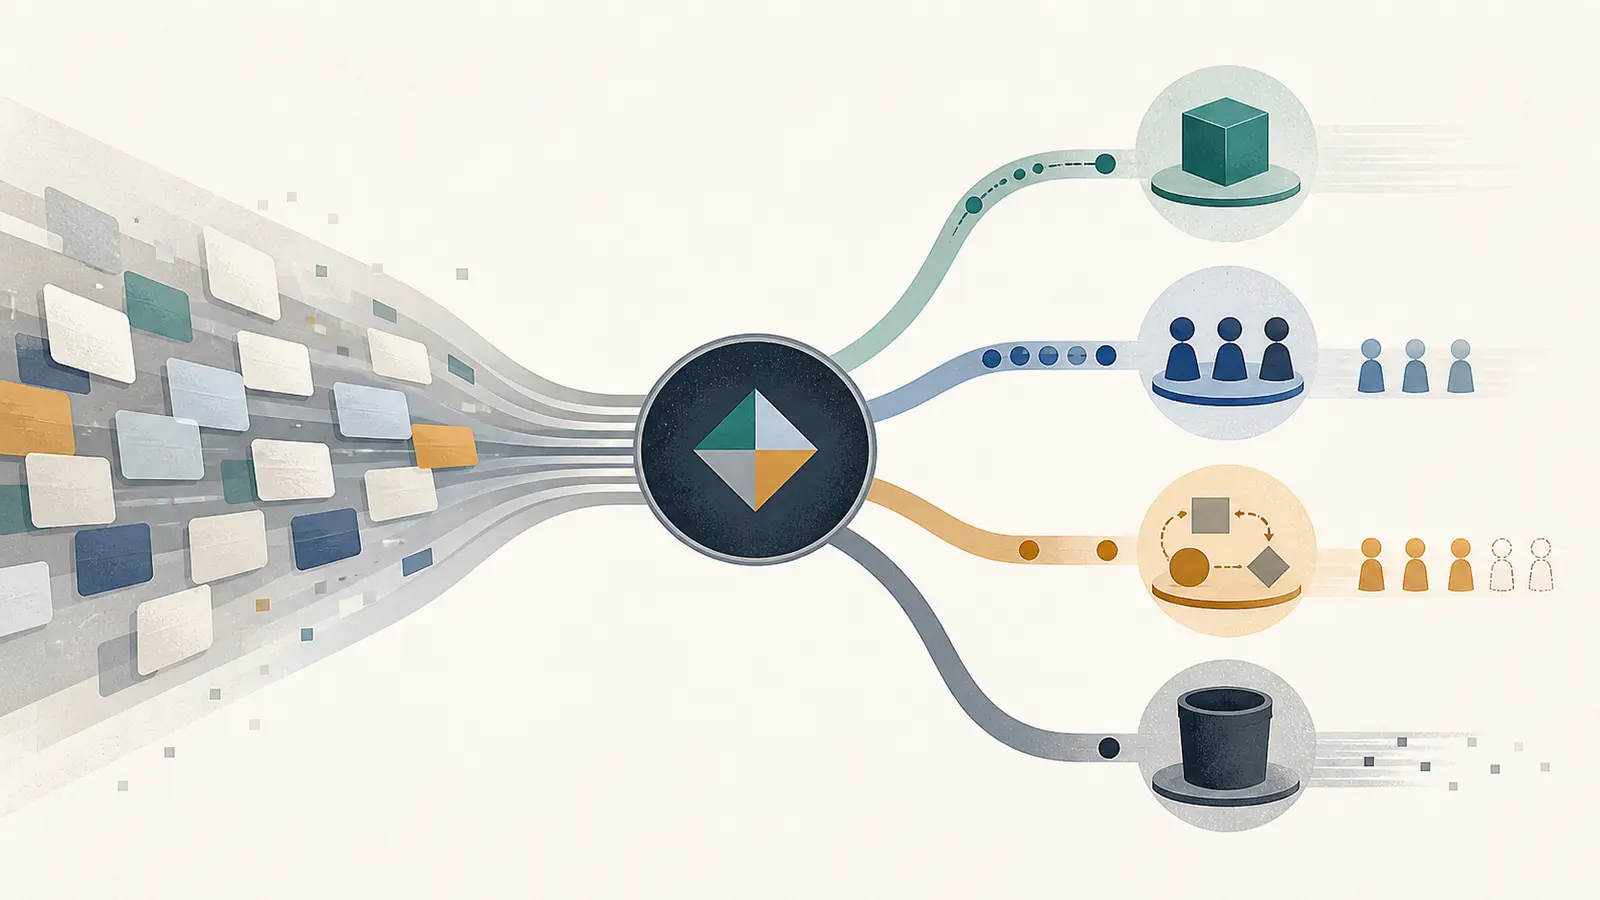
The prototype looked close enough to ship, until the team asked what its confidence score should actually do. A score is a signal. It is not a routing policy.
When I taught product managers to move from writing specs to building and shipping, the recurring failure was often an undefined shipping decision rather than the model (Marius Manolachi's AI teaching work). That observation is not a failure rate. It is a warning about the question you ask next: what would make this workflow acceptable to run?
The worked result: no threshold was viable under both limits
In a 24-case audit using the public Iris classification dataset as a bounded proxy, I compared fixed thresholds against two commercial constraints: no more than 5% error among auto-routed cases and no more than eight cases sent to a reviewer per batch.
| Policy | Auto-coverage | Selective risk | Review cases | Modeled human and machine minutes | Decision |
|---|---|---|---|---|---|
| Full automation | 100.0% | 16.7% | 0 | 4.8 | Reject |
| Confidence >=0.70 | 75.0% | 11.1% | 6 | 27.6 | Reject risk |
| Confidence >=0.80 | 58.3% | 7.1% | 10 | 42.8 | Reject risk and capacity |
| Confidence >=0.90 | 37.5% | 0.0% | 15 | 61.8 | Reject capacity |
| Full review | 0.0% | 0.0% | 24 | 96.0 | Too expensive for this assumption |
The decision is redesign the workflow or validation layer, not “try 0.85 next.” A threshold of 0.90 looks safe on this small sample, but it creates almost twice the review load the operating model can absorb. A threshold of 0.70 fits the queue and misses the error limit.
This is the same trade-off selective-prediction research makes explicit: coverage is the share of cases the system answers, while risk is the error rate on the cases it answers. Lowering a threshold usually increases coverage and risk together. ReCoVERR's paper defines those metrics and selects thresholds against a risk tolerance. The ACL selective-prediction paper frames abstention as refusing low-confidence predictions and connects confidence estimation with accuracy-efficiency trade-offs.
What should you measure before choosing a route?
Start with a labeled case set and write the decision limits before looking at thresholds.
- Define success. Write the label that determines whether the output is correct. Do not use “looks good.” In the proxy, success meant the predicted Iris class matched the public label.
- Freeze the confidence signal. Record the model, prompt, version, score definition, and any calibration step. A score from a different prototype is a different experiment.
- Record validation failures separately. Missing fields, malformed inputs, unsupported categories, stale evidence, and policy violations are route conditions, not ordinary low-confidence cases.
- Set the stakes. Decide which errors are cheap to reverse and which actions need approval. High-stakes or irreversible actions should not become automatic because a number is high.
- Set reviewer capacity. Count minutes, not headcount. In the worked artifact, each review took four modeled minutes and the batch limit was eight cases.
- Compare fixed policies. Use full automation, a few predeclared thresholds, and full review. Add more thresholds only if the result is close enough to change the decision.
The confidence score matters only after these fields exist. Microsoft Learn's human-in-the-loop design module puts confidence-threshold escalation beside asynchronous approval for high-stakes actions, feedback collection, and audit workflows. That is the right architecture distinction: confidence can decide who sees a case next; it does not by itself grant authority to act.
How do you read a risk-coverage result?
Treat each threshold as a business policy with a cost, not as a model setting with a “best” value.
The worked proxy has four errors. Full automation exposes all four. At 0.70, two errors remain in the auto route. At 0.80, one remains. At 0.90, none remain in this sample, but 15 of 24 cases need review.
That last row is not a victory unless the reviewer can handle it. The system has exchanged model error for human queue pressure. In production, measure at least:
- selective risk among auto-routed cases;
- auto-coverage across all cases;
- review volume and reviewer minutes;
- correction or reversal rate after review;
- time to final decision;
- category or subgroup differences;
- validation failures and unsupported inputs.
The test also exposed category imbalance. At threshold 0.80, setosa had 0.0% selective risk across seven auto-routed cases, versicolor had 0.0% across four, and virginica had 33.3% across three. A global 7.1% risk figure hides that uneven exposure.
This is why calibration belongs in the redesign path. The ACL paper studies confidence estimators, and ReCoVERR's results depend on confidence being higher for correct predictions than incorrect ones. Barnes and Barnes make abstention an explicit fraction-selection problem in a different regression domain, which is useful corroboration but not a recipe for this classifier. A raw model score that ranks one category badly is not ready to control an action boundary.
When should low confidence trigger more evidence instead of a reviewer?
Add an evidence-verification step when the workflow can cheaply gather a relevant, auditable signal that may resolve the uncertainty.
ReCoVERR is a research example in vision-language reasoning. When its model is uncertain, it asks related questions, keeps evidence that is reliable and relevant, and checks whether the evidence supports the original answer before deciding whether to answer or abstain. The authors report higher coverage without decreasing accuracy on their tested benchmarks. That does not prove the same repair will work for your workflow. It gives you a concrete redesign hypothesis: the prototype may be missing a validation or retrieval step, not a better threshold.
For a business workflow, an evidence step might mean checking the source-of-record, confirming an identifier, requesting a missing field, or comparing two independent signals. It must have a stopping rule. If evidence is missing, contradictory, or too expensive, route to a person.
What is the routing matrix after a failed prototype?
Use the case state first, then confidence, then operating capacity.
| Case state | Route | Release condition |
|---|---|---|
| Input or validation check fails | Review or reject input | The missing condition is repaired or a reviewer resolves it |
| Action is high-stakes or irreversible | Human approval | A separate risk review, approval path, and audit record exist |
| Valid, low-stakes, score above an approved threshold | Automate | Selective risk, subgroup limits, and reviewer capacity all pass |
| Valid but below threshold | Review | Reviewer SLA and correction process are staffed |
| No threshold meets the limits | Redesign workflow or validation | A new labeled case set can falsify the redesign |
| Redesign still fails the limits | Stop the use case | The use case cannot meet its error and capacity constraints |
The matrix prevents a common mistake: treating “review everything” as a safe default without pricing it. Full review may be correct for a high-stakes workflow. It may also be a manual process with an AI prefill, not automation. Name the route honestly.
How do you decide between routing, redesign, and stopping?
Use this order of decisions:
- Automate only if a fixed threshold meets the approved error limit, relevant subgroup limits, validation rules, and reviewer-capacity model.
- Route to review if the unresolved cases are genuinely ambiguous, the queue fits capacity, and the reviewer can correct the error before an irreversible action.
- Redesign the workflow if confidence is poorly ordered, a category has concentrated errors, evidence is missing, or review volume is too high. Change the input contract, retrieval or validation step, action boundary, or scope.
- Stop if one redesign cycle still cannot produce a feasible threshold or a staffed review route. Do not fund a second prototype just to avoid saying that the use case is not ready.
The falsifiable condition is simple: on a new labeled set, a viable confidence route must produce selective risk of 5% or less, no more than eight review cases per batch, and no relevant subgroup above its approved risk limit. If it cannot, the next action is redesign or stop, not another arbitrary threshold.
What does this proxy prove, and what does it not prove?
It proves that a routing decision can be made inspectable. It does not prove that the Iris proxy is representative of your workflow or that a 0.90 score means 90% correctness.
The sample has 24 fixed cases, selected eight per class from a 150-row public dataset. The prototype uses fixed centroids and an uncalibrated distance score. The cost model assumes four reviewer minutes and 0.2 machine minutes per case. Reviewer correctness is assumed for the comparison. None of those values should be copied into a production business case without replacing them with measured values.
What you can copy is the artifact: label the cases, define the score, set the error and capacity limits, compare fixed routes, inspect categories, and write the stop rule before approving more engineering.
For the broader architecture context, start with the AI architecture decisions parent, then compare the route with how to evaluate an AI agent and why AI evals pass while users still fail. If you have a failed prototype, the next useful session is not another demo. It is a labeled case review with the person who owns the decision. Marius Manolachi's AI capability work is built around making existing people capable of building and shipping on their own work. Start with the route your evidence can defend.
Questions people ask next
Should a high-stakes AI action ever route on confidence alone?
No. Keep human approval for irreversible or regulated actions until a separate validation set, approved risk limit, reviewer workflow, and audit record show that the route is safe for that action.
What if the confidence threshold passes risk but overloads the reviewer?
It is not a viable route. Reduce scope, improve validation or evidence gathering, change the workflow, or stop. A threshold that creates an unstaffable queue has not solved the prototype failure.